The stack for physical AI
From real-time running to cognition, evaluation and evolution, Hylo builds every layer of physical AI on one execution kernel. These pages show how to use each layer and how to extend it.
The Hylo stack
Six layers, top to bottom, all built on one execution kernel. Each card names where the layer lives and where to read about it.
-
6 · Workbench
Run tasks, replay every episode and approve releases in one workspace. Hylo Studio (hylo-studio).
-
5 · Evolution
Turn experience into stronger versions, each one tested before release. Learners turn development runs into sealed artifacts; campaigns compare candidates with the current version on separate episodes and promote what passes, after a person approves. Learn, Evolve (hylo-learn, hylo-evolve).
-
4 · Evaluation
Measure every policy against the same standard. Protocols fix the episodes, seeds and timing; scorecards carry Wilson intervals; leaderboards compare policies. Hylo Bench, Eval (hylo-bench, hylo-eval).
-
3 · Cognition
Use what the robot has seen and done to choose its next step: policies of every family, steered by memory, critics, skills, planners and success judges. Memory, Agents, Policies (hylo-memory, hylo-agents, hylo-policies).
-
2 · Runtime
Run policies on robots in real time, within the safety limits you set. A workcell runs the same episode loop as the benchmark, behind the SafetyShield and an operator channel. Hylo Serve (hylo-serve).
-
1 · Kernel
One execution kernel connects models, simulators and robots through versioned plugin contracts, and keeps every run in one store. Hylo Core, Plugins (hylo-core, hylo-plugins).
Results recorded so far
| What | Result | Where |
|---|---|---|
Reference policies on mujoco-reach (100 held-out episodes) |
mpc 86%, flow + steering 84%, bc + temporal ensemble 83%, flow 83%, bc 71%, tokens 68%, knn 64%; the IK expert 100% | Leaderboard |
| A gated campaign on MuJoCo reach | held-out success 0.40 → 1.00 after promotion | Campaigns |
| SmolVLA on LIBERO-10, as a robot would run it | 0.20 success with the world waiting for each call, 0.05 in real time (2 tasks × 10 init states, 19 hold steps per episode; too few episodes for a conclusion) | RFC-0005 |
| A success judge for LIBERO-10 trained from traces | AUC 0.92 against simulator outcomes (600 episodes) | Experiment record |
These are small studies, recorded with their commands and versions. The plugin catalogue says which parts have run end to end and which have not.
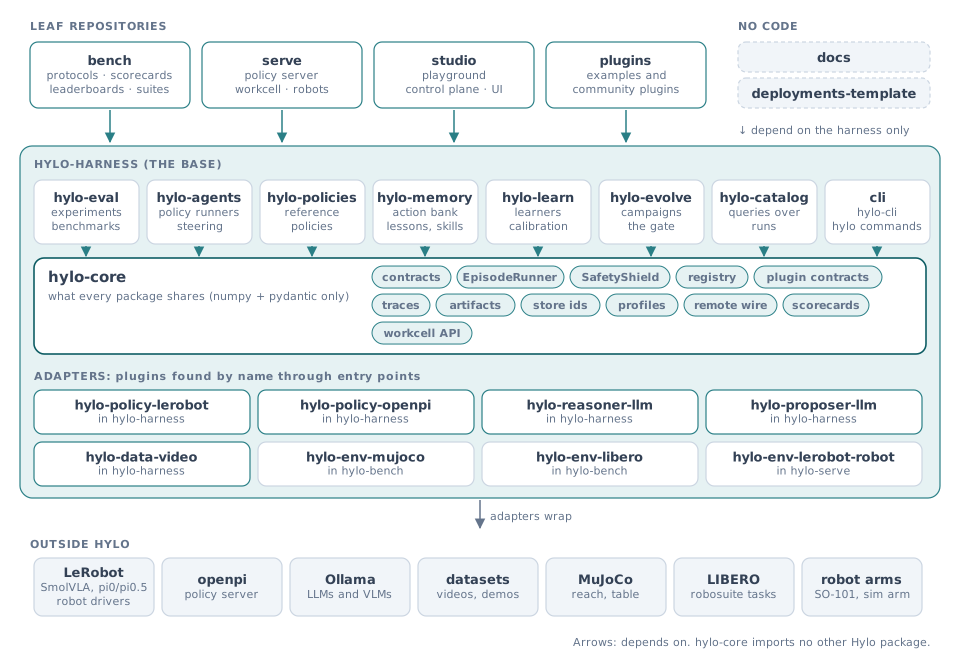
The repositories
| Repository | Layers | What it holds |
|---|---|---|
| hylo-harness | kernel, cognition, evaluation, evolution | contracts and the execution kernel, the evaluation engine, agents, memory, learning, campaigns, the run catalog and store, adapters to policy stacks and LLMs, the hylo command |
| hylo-bench | evaluation | protocols, scorecards and leaderboards; the MuJoCo and LIBERO suites and their setup |
| hylo-serve | runtime | policy server, workcell, real-time runner, operator channel, robot adapters |
| hylo-studio | workbench | run explorer, live sandbox, campaigns and approvals, the control plane for workcells |
| hylo-plugins | kernel | example and community plugins, written the way a third party would |
| hylo-deployments-template | runtime | template for a lab's private configuration: workcells, calibration, safety limits |
| hylo-docs | this site |
Every leaf builds on the harness alone and cooperates with the others through formats defined in hylo-core
(repository structure).