Benchmarking
hylo-bench scores policies. A protocol fixes everything about an evaluation except the policy. Running a policy under it writes a scorecard. Scorecards of one protocol form a leaderboard, and any two of them can be compared episode by episode.
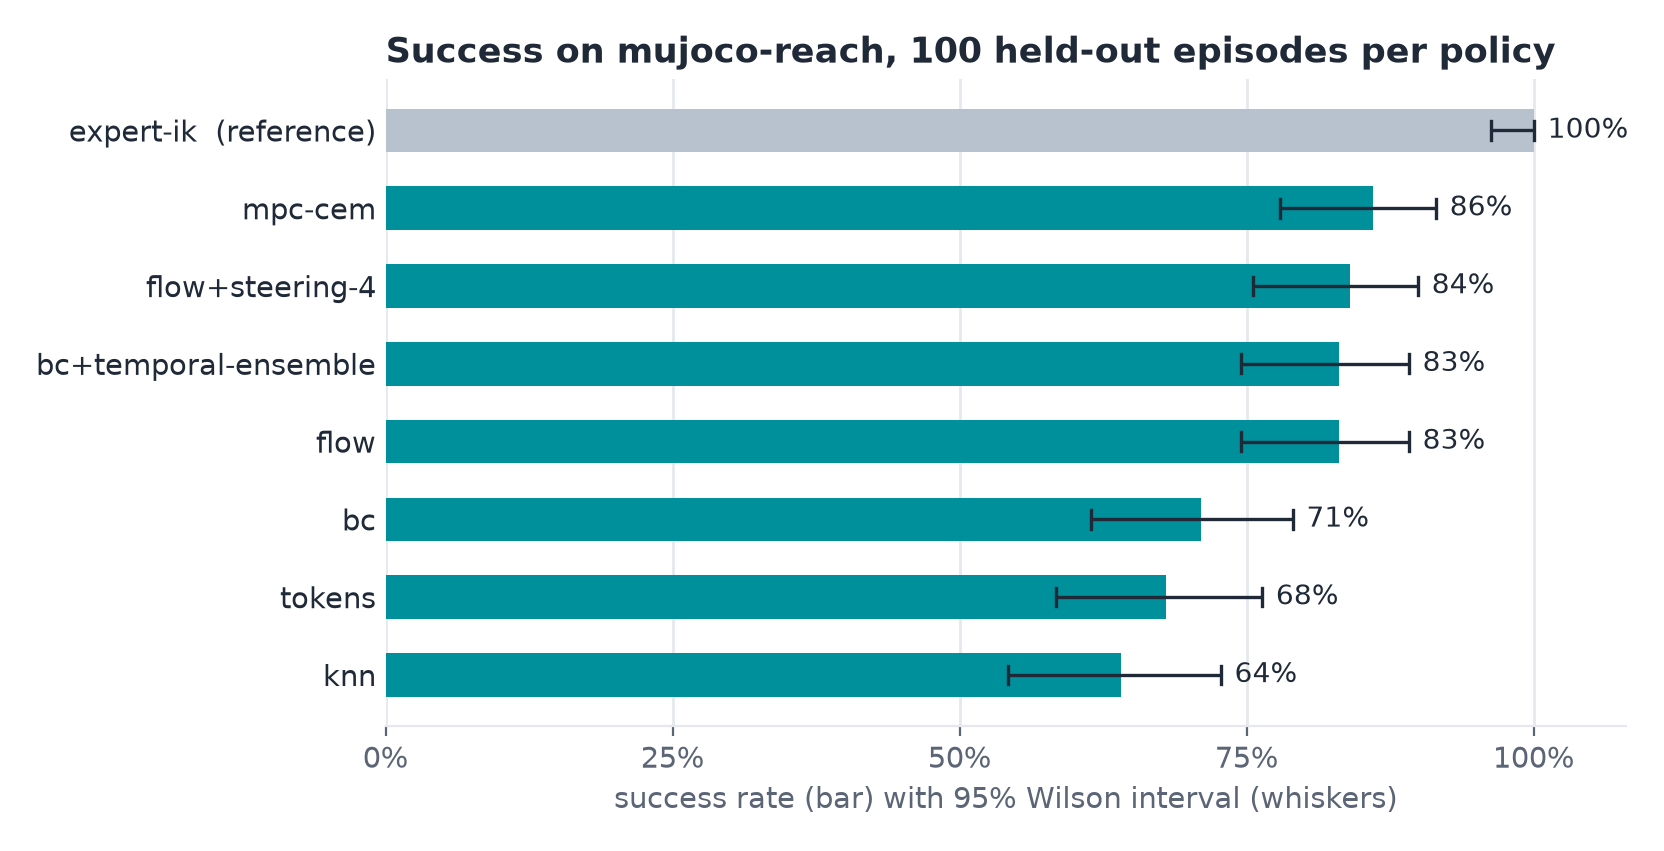
The mujoco-reach leaderboard of the reference policies: 100 held-out episodes each, 95% Wilson intervals.
Protocols vs experiments
An experiment config says what to run: benchmark and split, environment, agent,
safety, trace, timing. A protocol is an experiment with the agent left out, frozen and versioned
(hylo.protocol/v0.1):
| Experiment config | Protocol | |
|---|---|---|
| Agent | part of the config | the only free input (--policy) |
| Who writes it | anyone, for any run | ships with hylo-bench; a change is a new version |
| Identity | config digest | protocol name, version and digest |
| Result | a run (evallog.json, traces) |
a run plus a scorecard |
| Comparable with | runs of the same benchmark split | every scorecard with the same protocol digest |
Because only the policy varies, two scorecards with the same protocol digest measured the same episodes: the same tasks, init states and seeds, the same safety limits, the same timing. That makes them comparable pair by pair, not only by their means. See Protocols for the fields and the built-in protocols.
Scorecards
A scorecard (hylo.scorecard/v0.1, defined in hylo.core.scorecard so that every repository can read it)
is self-contained:
| Field | Content |
|---|---|
protocol, protocol_version, protocol_digest |
what was measured |
policy, agent |
the display name, and the agent spec that ran |
metrics |
success_mean, steps_mean, safety_interventions_mean, n_episodes, n_scored, ... |
success_ci95 |
the 95% Wilson score interval on the success rate |
per_task |
success and episode count per task |
episodes |
per-episode success keyed task#seed, which pairwise comparison uses |
run_dir, config_digest, code |
the run it came from, the package versions and the git commit that ran |
notes, created_at |
free text (--notes), and when it was written |
hylo bench run writes the run to OUT/runs/ and the scorecard to OUT/scorecards/<protocol>/<policy>.json
(--out, default the current directory).
Statistics
Intervals. The success interval is the Wilson score interval at 95%. Unlike the normal approximation, it stays inside [0, 1] and behaves at 0% and 100% success: 100 successes in 100 episodes give [96.3%, 100%], not [100%, 100%].
Pairwise comparison. hylo bench compare CANDIDATE BASELINE pairs the two scorecards' episodes on task#seed
and runs a one-sided exact McNemar test on the discordant pairs (the alternative: the candidate succeeds more
often). Episodes that both policies solve, or both fail, say nothing about which is better and drop out. Pairing
is far more sensitive than comparing two means. On mujoco-reach, flow + steering against plain BC: 18 wins, 5
losses over 100 pairs, p = 0.005, although the two Wilson intervals overlap. Scorecards of different protocol
digests are refused.
The improvement gate uses the same test, with sequential looks and vetoes.
Commands
uv run hylo bench list                                     # built-in protocols, their versions and digests
uv run hylo bench show mujoco-reach                        # one protocol, with its digest
uv run hylo bench run mujoco-reach --name ik-0.3 \
    --policy '{"type": "baseline.planar_ik", "params": {"kp": 0.3}}'
uv run hylo bench leaderboard                              # every scorecard under ./scorecards, per protocol
uv run hylo bench compare scorecards/mujoco-reach/ik-0.3.json scorecards/mujoco-reach/bc.json
All options: CLI reference. Next: protocols and leaderboards.
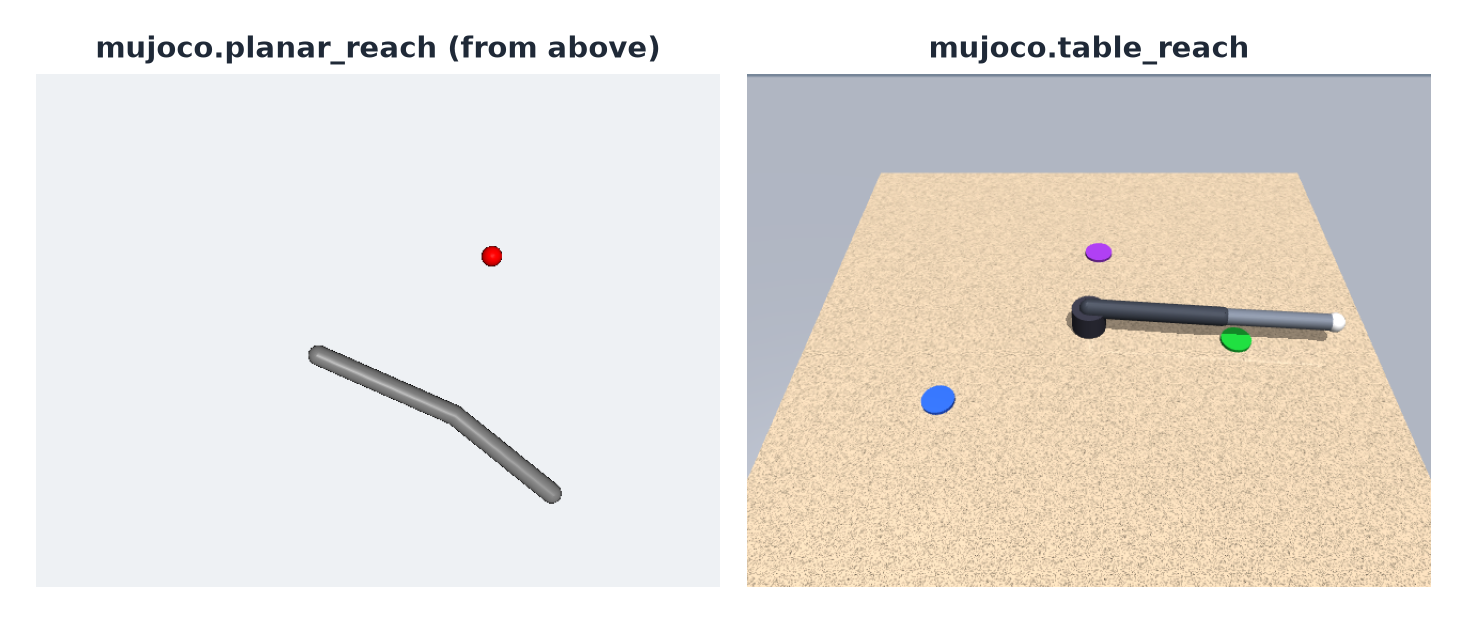
The MuJoCo environments of hylo-env-mujoco: planar reach (the mujoco-reach protocol) and the table scene of the examples.